Data governance is the set of policies, roles, processes, and technologies that make sure an organization’s data is accurate, secure, and available for trusted decision-making. The goal is simple even when the work isn’t: keep data trustworthy enough that people actually use it. That comes down to four building blocks working together: the people who own the data, the policies that define the rules, the processes that enforce them, and the technology that makes enforcement possible at scale.
TL;DR:
- The success of data governance relies on clear alignment of policies, roles, processes, and technology, with an emphasis on defining ownership first.
- Implementing governance iteratively on high-value domains allows organizations to demonstrate tangible results like reduced duplicates and faster reconciliation.
- Governance must connect strategy to operations through well-defined roles such as data owners, stewards, and councils, avoiding bottlenecks caused by centralization.
- Utilizing integrated tools like data catalogs, lineage systems, and access controls supports scalable enforcement of policies across organizational systems.
- Without measurable KPIs and ongoing data quality management, governance programs risk losing support despite technological investments.
Table of Contents
- What Data Governance Covers and Why It Exists
- What Are the Core Pillars of Data Governance?
- Who’s Responsible for Data Governance? Roles Explained
- How Do You Implement Data Governance? A Step-by-Step Framework
- Data Governance vs. Data Management: What’s the Difference?
- What Business Benefits Does Data Governance Deliver?
- What Are the Biggest Challenges in Data Governance?
- What Tools and Technologies Support Data Governance?
- How Does Governance Work in Spreadsheet-Driven Teams?
- What Do Real Data Governance Programs Look Like?
- What Regulations Affect Data Governance Requirements?
- How Do You Measure Data Governance Success?
- How Are Data Governance and Data Quality Connected?
- Ready to Put Data Governance Into Practice?
- A Pragmatic Plea for Iterative Governance
- Sources
What Data Governance Covers and Why It Exists
Data governance isn’t a single policy or a one-time project. It covers the entire lifecycle of data, from the moment it’s created to the day it’s finally deleted.
Think about a customer record. It gets created when someone fills out a form. It gets stored in a CRM. It gets used by sales, marketing, and finance, each pulling it into a different report. It gets shared with a partner system. Eventually, it gets archived, or it should be deleted under a retention policy nobody remembers writing. Every one of those steps is a place where data can go wrong, get duplicated, or drift out of sync with reality.
Governance exists because none of that happens correctly by accident. Without rules about who owns a record, what “active customer” actually means, or how long you keep transaction history, every team ends up with its own private version of the truth. That’s how you end up with three departments reporting three different revenue numbers off the same underlying data.
Data governance is best understood as the set of principles, policies, and processes that guide responsible data use across that entire lifecycle. It defines who’s accountable, who can access what, how accuracy gets checked, and how usability gets preserved as data moves through systems. That’s the practical difference between data that’s collected and data that’s actually governed.
Governance also does something less obvious: it connects strategy to daily operations. Leadership sets a goal like “become a data-driven organization,” but that phrase means nothing until it’s translated into rules an analyst follows on a Tuesday afternoon. Governance is that translation layer. It turns board-level intent into:
- Naming conventions that keep “Q1” and “quarter one” from splitting your dashboards
- Access rules that stop finance data from leaking to teams that shouldn’t see it
- Quality checks that catch a broken pipeline before it corrupts a report
- Retention schedules that keep you compliant instead of guessing
Without that bridge, strategy stays a slide deck. With it, strategy becomes something a data engineer can actually build against.
What Are the Core Pillars of Data Governance?
Every functioning governance program rests on four pillars. Skip one, and the whole structure gets shaky, because each pillar depends on the others to work.
- Policies and standards. This is the rulebook: naming conventions, data classification (public, internal, restricted), and retention schedules that say how long data lives before it’s archived or purged.
- Processes and workflows. Policies mean nothing without repeatable action. This includes metadata documentation, quality remediation workflows when bad data is flagged, and lineage tracking that shows where a number actually came from.
- People and roles. Someone has to own the outcome. This pillar covers accountability structures, stewardship assignments, and a governance council that resolves disputes and sets priorities.
- Technology. Catalogs, lineage tools, access controls, and monitoring systems are what let policies and processes run at a scale no spreadsheet or manual checklist can handle.
A widely cited governance framework breaks the discipline down into exactly these four components: defined policies, repeatable processes, enabling technology, and organizational accountability structures. Miss the technology piece and your policies stay theoretical. Miss the people piece and your technology enforces nothing because nobody’s watching the exceptions.
Pro Tip: Don’t try to write the perfect policy document before you’ve assigned a single steward. Pick one data domain, assign an owner, and let the policy get written around real decisions that domain owner has to make. Policies written in a vacuum get ignored in practice.
Here’s what trips people up: they treat “technology” as the starting point, buying a catalog tool before anyone has agreed on what a “customer” even means across departments. Tools amplify whatever governance maturity already exists. A catalog on top of undefined data just gives you a searchable mess instead of an unsearchable one. Standards and roles come first; the platform comes second.
Who’s Responsible for Data Governance? Roles Explained
Governance fails most often not because the rules were wrong, but because nobody was actually accountable for enforcing them. Clear roles fix that.
- Data Governance Council (or steering committee). This group sets overall direction, resolves cross-team conflicts (like when marketing and sales disagree on what counts as a “qualified lead”), and approves policy changes.
- Data Owners. Each significant dataset or domain, customer data, product data, financial data, needs a named owner accountable for its accuracy and appropriate use. This is usually a business role, not a technical one.
- Data Stewards. Stewards do the operational work: maintaining metadata, running quality checks, chasing down the source of a broken field, and making sure standards actually get followed day to day.
A commonly used role structure pairs a steering council with data owners and stewards this way, splitting strategic oversight from operational execution. Many organizations map these roles using a RACI model (Responsible, Accountable, Consulted, Informed) so it’s clear, for example, that a steward is Responsible for fixing a data quality issue while the owner is Accountable for the outcome.
The mistake to avoid is over-centralizing every decision at the council level. That slows everything down and turns governance into a bottleneck instead of an enabler. Better to give domain-aligned owner and steward pairs real authority over their own datasets, with the council stepping in only for cross-domain conflicts or policy-level changes.
How Do You Implement Data Governance? A Step-by-Step Framework
You don’t need a fully mature governance program before you get value from one. Most successful rollouts follow a similar sequence, starting narrow and expanding once the model proves itself.
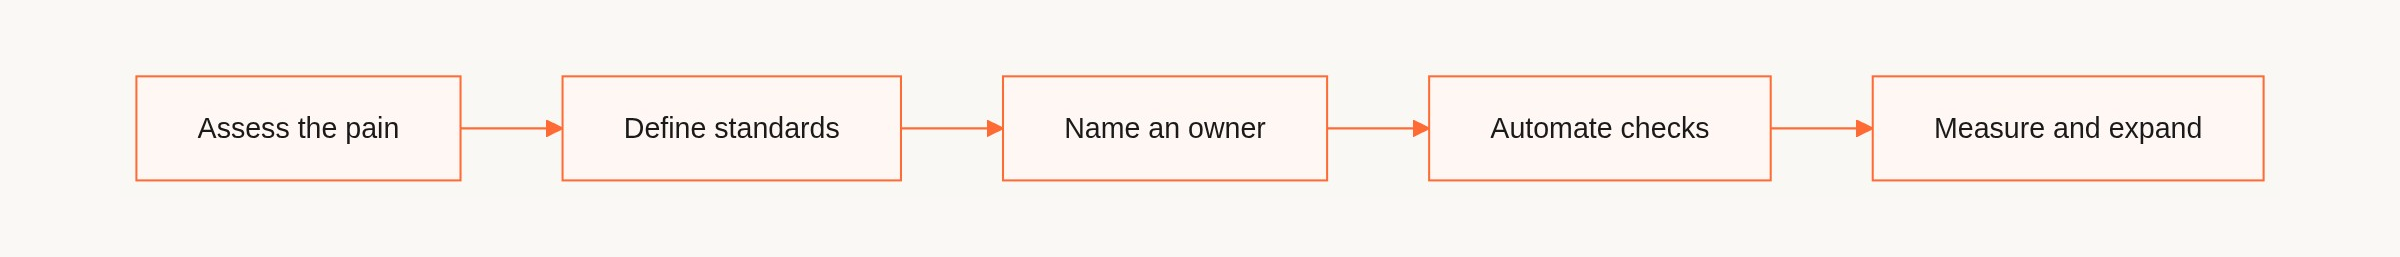
- Assess your current state and set business-aligned goals. Before writing a single policy, find out where your data actually breaks. Interview the teams who complain loudest about bad numbers. Identify which datasets get manually reconciled every month, because that’s where the pain (and the ROI) lives.
- Define policies, standards, and measurable KPIs. Write down what “accurate” and “complete” mean for your priority dataset. Set targets you can actually track, like reducing duplicate customer records by a specific percentage, rather than vague goals like “improve data quality.”
- Assign roles and pilot on one critical domain. Pick a single high-value area, customer data is a common starting point, and name an owner and steward before you touch a single tool. Resist the urge to govern everything at once.
- Deploy core technology and automate enforcement. Bring in a data catalog, lineage tracking, and quality checks scoped to your pilot domain. Where possible, automate the enforcement: flag duplicate records automatically instead of relying on someone to notice them manually.
- Measure impact, communicate wins, and iterate. Show the numbers. If duplicate records dropped or reconciliation time fell, tell the organization in concrete terms, then use that proof to justify expanding governance to the next domain.
That pilot-first sequence isn’t just a suggestion. It’s the pattern most governance programs follow when they succeed: pick a high-value domain, prove value quickly, then scale. Programs that instead try to govern every dataset in the organization simultaneously tend to stall under their own complexity before they deliver anything measurable.
One practical note on sequencing: don’t wait for perfect technology before assigning roles, and don’t wait for perfect roles before running a pilot. Governance is iterative by nature. The team that ships a rough policy and a named owner in month one will outperform the team still drafting its “comprehensive framework” in month six.
Data Governance vs. Data Management: What’s the Difference?
Governance and management get used interchangeably, but they answer different questions. Governance answers “why” and “who.” It sets the rules, defines accountability, and determines who’s allowed to touch what. Management answers “where” and “how.” It’s the technical execution: building the pipelines, running the storage systems, and processing the data those rules apply to.
Data governance is distinct from data management in exactly this way: governance sets the rules, while management implements them through technical work like metadata management, master data management, and quality assurance processes.
Here’s what that looks like in practice. Governance decides that customer records must include a verified email field and defines who owns that standard. Data management is the pipeline engineering team that actually enforces the field-level validation in the ETL job. Governance sets an access policy saying only finance can see payroll data. Management is the infrastructure team configuring the actual role-based permissions in the database. Neither works without the other; governance without management is a policy nobody enforces, and management without governance is infrastructure with no rules to follow.
What Business Benefits Does Data Governance Deliver?
Governance isn’t overhead. Done well, it pays for itself in a handful of measurable ways.
- Faster, more reliable analytics. When everyone agrees on what a metric means and where it comes from, decisions stop getting delayed by “which number is right” debates.
- Lower compliance and security risk. Clear policies on access and retention mean fewer surprises during an audit and fewer accidental exposures of sensitive data.
- Operational efficiency. Less time spent manually reconciling spreadsheets across departments means more time spent on actual analysis.
- A real foundation for AI. Models trained on inconsistent, poorly governed data produce inconsistent, poorly trusted results.
Implementing an effective data governance strategy improves data quality, visibility, security, and compliance, which in turn enables trusted analytics and safer AI development. That last point matters more every year: any AI initiative is only as reliable as the governed data feeding it.
The efficiency gains compound quickly once teams stop rebuilding the same reconciled report every month. Real-time, governed data views let leaders make decisions off current numbers instead of last week’s manual export, and that shift alone changes how fast a team can respond to a problem.
What Are the Biggest Challenges in Data Governance?
Most governance programs don’t fail because of bad technology. They fail because of predictable, fixable friction.
- Resistance to change. People don’t want another layer of process on top of their existing workload. Counter it with a pilot that shows a quick, visible win rather than a mandate handed down from above.
- Siloed definitions. When marketing’s “active customer” doesn’t match sales’ definition, trust erodes fast. Centralize the core definitions, even if you federate the day-to-day stewardship.
- Tool fragmentation. A catalog that doesn’t talk to your lineage tool doesn’t talk to your access control system creates more manual work, not less. Choose components that integrate rather than isolated best-of-breed tools that don’t share data.
- Program fatigue. Governance initiatives lose funding when nobody can point to a business result. Tie every governance metric back to a dollar figure or a risk avoided, and keep reporting it.
Pro Tip: If your governance program can’t name one metric it improved in the last quarter, that’s the problem to fix before adding another policy document. Momentum comes from visible wins, not thicker binders.
What Tools and Technologies Support Data Governance?
You don’t need to evaluate every category at once, but it helps to know what each one actually does before a vendor conversation starts steering the decision for you.
Data catalogs and metadata platforms give you a searchable inventory of what data exists, what it means, and who owns it. Lineage and observability systems trace a number back to its source, so when a dashboard looks wrong, you can find out exactly where it broke instead of guessing. Access control and auditing systems enforce who can see or change what, and log it for compliance purposes. Quality monitoring and remediation tools flag bad data automatically and, in more mature setups, fix common issues without a human in the loop.
One practical guideline: favor open metadata standards and tools with strong APIs, since that’s what lets a catalog integrate cleanly with your existing pipelines instead of becoming its own isolated silo.
How Does Governance Work in Spreadsheet-Driven Teams?
Spreadsheets are where governance quietly falls apart for most teams, and it’s rarely anyone’s fault. A single sheet gets copied, edited, emailed, and copied again until nobody knows which version is current. There’s no lineage showing where a number came from. Two departments define “closed deal” differently in two different tabs, and both think they’re right.
Spreadsheets create governance gaps in three specific ways: multiple untracked copies, no built-in lineage, and inconsistent definitions across users who never see each other’s version. Closing those gaps doesn’t require abandoning the spreadsheet. It requires adding the structure around it.
- Assign clear ownership to the source spreadsheet, not the five copies floating in people’s inboxes.
- Use two-way sync so updates flow back to the original source instead of creating another orphaned copy.
- Turn on audit logs so you can see who changed what and when.
- Apply role-based access so sensitive columns aren’t visible to everyone with the link.
The operational payoff is real: fewer manual handoffs, faster root-cause analysis when a number looks off, and an audit trail that satisfies compliance without extra manual documentation. Data connectors that merge multiple spreadsheets and tools into one governed record are one practical way teams close this gap without rebuilding their entire workflow from scratch.
What Do Real Data Governance Programs Look Like?
Governance looks different depending on the industry, but the underlying discipline is the same: define ownership, enforce standards, track lineage.
In healthcare, governance often centers on patient record accuracy and access restriction. A hospital system might govern who can view diagnostic data, how long records are retained, and how data moves between departments without duplicating or exposing protected health information.
In financial services, governance frequently focuses on transaction lineage and regulatory reporting. A bank needs to trace a reported number back through every system it touched, because auditors will ask, and “we’re not sure” isn’t an acceptable answer.
In retail and e-commerce, governance shows up in inventory and customer data consistency. When a warehouse system, an e-commerce platform, and a CRM all track the same SKU differently, governance is what forces a single definition and a single source of truth across all three, often through a unified warehouse and inventory application that ties the systems together.
In manufacturing, governance often governs sensor and quality-control data, ensuring that production metrics feeding into safety or compliance reports are accurate and traceable back to the specific machine and shift that generated them. Across every one of these examples, the pattern repeats: pick the domain that causes the most pain, govern it first, then expand.
What Regulations Affect Data Governance Requirements?
Regulatory compliance is one of the strongest business cases for governance, because the penalties for getting it wrong are specific and expensive.
In healthcare, HIPAA requires strict controls over who can access patient data and how it’s stored, transmitted, and audited. A governance program in a healthcare setting has to bake those access rules directly into its role definitions, not treat them as an afterthought.
In any organization handling data from European residents, GDPR imposes requirements around consent, the right to be forgotten, and breach notification timelines. That means your retention policies and data deletion processes aren’t optional documentation exercises. They’re operational requirements a steward has to actually execute.
Financial services face their own layer of reporting and audit requirements, often demanding full lineage from a filed report back to its raw source data. The obligations increasingly run past legal compliance too, into fairness and accountability questions raised by cross-border data flows and AI systems trained on that data.
The practical takeaway: compliance isn’t a separate checklist that sits next to governance. It’s one of the primary reasons governance policies get written in the first place. A retention rule that satisfies GDPR and a data quality check that catches a compliance-reportable error are governance doing exactly what it’s supposed to do.
How Do You Measure Data Governance Success?
Governance programs that survive budget reviews are the ones that can point to numbers, not just policy documents.
Common KPIs include the data quality score for a given domain (often tracked as a percentage of records passing validation rules), the time it takes to resolve a data quality incident from flag to fix, and the percentage of critical datasets with a named, active owner. Some teams also track policy compliance rates, how consistently naming and classification standards actually get followed, and audit readiness, measured as the time it takes to answer a lineage question during a review.
The specific metrics matter less than the discipline of tracking any of them consistently. A governance program with no KPIs has no way to prove it’s working, which makes it the first thing cut when budgets tighten. A program tracking even two or three simple metrics, like reduced duplicate records or faster incident resolution, can point to a trend line and justify its own continuation.
Tie those metrics to a business outcome whenever possible. “Reduced duplicate customer records by tracking X” is a fine internal metric, but “reduced duplicate records, which cut reconciliation time from three days to four hours” is the version that gets a governance program funded for another year.
How Are Data Governance and Data Quality Connected?
Data governance and data quality management aren’t the same discipline, but they’re inseparable in practice. Governance sets the standard for what “good” data looks like, defining accuracy, completeness, and consistency requirements for a given dataset. Data quality management is the ongoing operational work of measuring data against that standard and fixing what falls short.
Without governance, quality management has no target to aim for; a team might clean data without ever agreeing on what “clean” actually means. Without quality management, governance is just a policy document with no way to verify anyone’s following it. The two work as a loop: governance defines the standard, quality processes measure against it, and the results feed back into governance to refine the standard over time.
This is also where stewards spend most of their operational time. A data steward doesn’t just document standards; they run the checks, chase down the source of a broken field, and report back on whether the domain is actually meeting the bar governance set for it. That feedback loop is what keeps a governance program from turning into a static binder nobody consults after the kickoff meeting.
Ready to Put Data Governance Into Practice?
Reading about governance and actually running it are two different problems, and the gap between them is usually a pile of disconnected spreadsheets nobody wants to touch. If your team is still emailing versions of the same file back and forth, that’s not a governance failure so much as a missing layer of structure.
Gainable reads your spreadsheets, whether that’s Excel, Google Sheets, or both, and merges them into one governed data model with a real application on top: authentication, audit logs, dashboards, and role-based access built in from the start. It also connects to tools like HubSpot, Stripe, Airtable, Salesforce, Jira, and Linear, merging everything into a single record by whatever key you choose, with source priority deciding which system wins when two of them disagree on the same field, and syncs both ways so the app writes back to the source instead of leaving it stale.
That’s governance’s core promise in practical form: one owner, one source of truth, a visible audit trail, and no more copy-paste loop between the person who owns the data and the team that needs it. If recurring reconciliation work is eating your week, Gaia Autopilot watches for anomalies and drafts the fixes for you to approve, with every trigger and outcome recorded in the action log, which is exactly the kind of automated enforcement a mature governance program is supposed to have.
Explore the Gainable platform to see how a spreadsheet-first team turns its existing data into a governed application without a six-month migration project.
A Pragmatic Plea for Iterative Governance
Governance done as a perfection exercise dies in committee. Pick one data domain, one measurable use case, and one owner willing to be accountable for it. Show a real number moving, fewer duplicates, faster reconciliation, before you write your next policy document.
The organizations that get this right treat governance as a balance of people, process, and automation, not a compliance project bolted onto a data team’s existing workload. Start small, measure honestly, and let the results argue for the next phase. That’s a better pitch to leadership than any framework diagram.
— Rickard
Sources
- What is data governance and why does it matter | TechTarget
- Data governance guide | Salesforce
- Data Governance | Databricks